Field note / Deep dive
Why I Self-Host Everything Now
I used to pay $700+/month in SaaS fees for a single project — Supabase 2XL compute at $410, Trigger.dev Pro at $210+ just for the concurrency we needed, plus per-second compute charges on top. Now I run the same stack — and more — for about €205/month on my own servers.
But the 70% cost savings isn't even the main reason I self-host everything.
It Started With Compliance, Not Philosophy
I didn't wake up one day and decide to self-host my entire infrastructure. The EU made that decision for me.
One of the biggest projects I work on at Veedoo is EUvsDisinfo — a platform for the European External Action Service that tracks and exposes Russian disinformation across Europe. 19,000+ documented cases, millions of annual users, content in 13 languages. I've written about building its evidence pipeline before. It's an EU-funded project, and EU-funded means one non-negotiable rule: all data must stay on EU servers. No exceptions. No US-hosted SaaS products. Nothing leaves EU jurisdiction.
That single compliance requirement forced me to start exploring what was possible outside the SaaS ecosystem. And once I started looking, I couldn't go back.
Discovering Coolify
In 2024, while searching for self-hosting options, I found Coolify — an open-source, self-hosted PaaS (Platform as a Service). Think Heroku or Vercel, but running on your own servers.
Coolify handles everything you'd expect from a modern deployment platform: Docker container orchestration, automatic SSL certificates via Let's Encrypt, reverse proxy configuration with Traefik, environment variable management, GitHub webhook-based auto-deployments, database provisioning — all through a clean web UI. You point it at a server, connect your repo, and deploy.
I started experimenting with it on Hetzner Cloud servers — a German hosting provider with excellent price-to-performance ratios, EU data centers, and NVMe SSD storage. First just for EUvsDisinfo's infrastructure. Then for internal Veedoo tools. Then for client projects.
By the end of 2024, Coolify was becoming the default for everything.
The Migration That Changed My Mind
The moment self-hosting went from "compliance requirement" to "this is clearly better" was the Baseloop migration.
I joined Baseloop as a founding engineer in late 2025. The product was running on Supabase's SaaS for the database, auth, and storage, and Trigger.dev's SaaS for background jobs. Both were hitting walls.
Supabase's connection pooling was capping out. Storage quotas were restrictive. And the pricing — we were on the 2XL compute add-on at ~$410/month just for the database.
Trigger.dev was worse. The Pro plan costs $50/month but only includes 200 concurrent runs. We needed at least 1,000. Getting there meant:
- Extra concurrency: 800 additional runs / 50 per bundle = 16 bundles × $10 = $160/month
- Per-second compute charges: Every run is billed by the second based on machine tier. Small 1x costs $0.0000338/sec. Medium 2x costs $0.0001700/sec. With 1,000 concurrent runs, this adds up fast.
- Invocation fees: $0.25 per 10,000 runs. On top of everything else.
Conservative estimate for the full SaaS stack: $700-800+/month. For one project.
And you're still subject to their limits. Their pricing changes. Their outages. Their roadmap decisions.
The Numbers That Convinced Me
Here's what the same infrastructure costs self-hosted on Hetzner Cloud:
| Service | Server | Specs | Monthly Cost |
|---|---|---|---|
| Supabase (self-hosted) | CCX43 | 16 vCPU, 64GB RAM, 360GB NVMe | €96.49 |
| Trigger.dev webapp | CPX52 | 12 vCPU, 24GB RAM, 480GB NVMe | €28.49 |
| Trigger.dev workers (×4) | 4× CPX42 | 8 vCPU, 16GB RAM each | €79.96 |
| Total | €204.94 (~$220) |
$700+ → €205. Same stack. More capability.
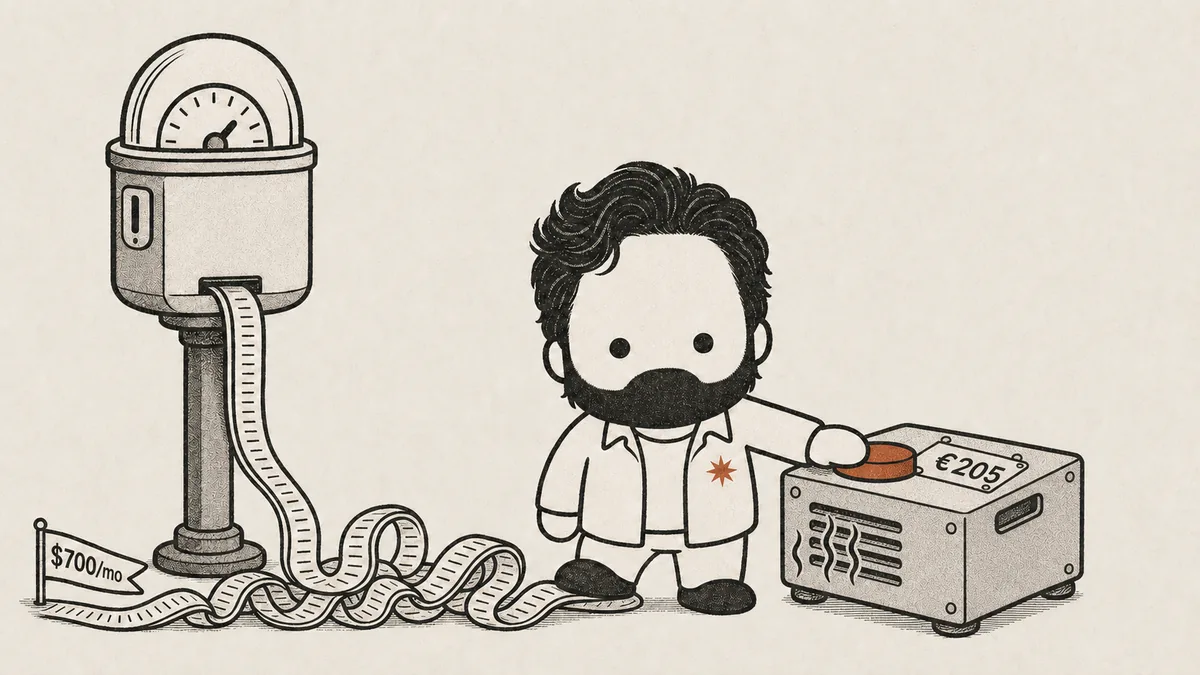
No concurrent run limits — we handle 1,000+ concurrent Trigger.dev runs across the 4 worker servers. No per-second compute charges — the servers are ours, run as much as you want. No connection pooling caps — we tune PostgreSQL however we need. Custom shared_buffers, work_mem, NVMe-optimized random_page_cost. Try doing that on Supabase SaaS.
The savings paid for the migration effort in the first month.
It's Not About the Money
The cost comparison makes a compelling argument, but honestly? Cost isn't even the most important reason.
Control is.
When something breaks on a SaaS platform, you open a support ticket and wait. When something breaks on your own infrastructure, you SSH in and fix it. Right now. At 2 AM if needed. You have access to every log, every config, every process. The problem is yours to solve, and that means it's yours to solve quickly.
I've been on both sides. Waiting for a SaaS provider to acknowledge an issue while your production system is down is one of the most frustrating experiences in software development. When it's your server, you might spend an hour debugging — but at least you're debugging, not waiting.
Data residency is yours to decide. Your data lives where you put it. Not where a SaaS company's cheapest AWS region happens to be. For EU-funded projects, this is non-negotiable. But even for projects without compliance requirements — why wouldn't you want to control where your users' data lives?
No vendor lock-in. No SaaS can deprecate the feature you depend on. No pricing page can change overnight. No acquisition can shut down the product you built your stack on. Your Docker Compose file doesn't have a pricing team.
Scaling is a config change. Need more database connections? Change a number in your PostgreSQL config. Need more background job throughput? Spin up another worker server. Need more storage? Attach a volume. No sales calls. No tier upgrades. No "contact us for enterprise pricing."
The Tools I Had to Build
Here's what nobody tells you about self-hosting: sometimes the tooling doesn't exist yet.
When I migrated Baseloop from Supabase SaaS to self-hosted, there was no tool that could do a full migration — schema, data, auth users, storage files, sequences, roles. Everything. So I built one.
supabase-sync — published on npm. It handles the entire migration:
- Database schema and data, using PostgreSQL's COPY format for performance
- Auth users with preserved bcrypt password hashes — nobody has to reset a password
- Storage files with concurrent uploads
- Automatic sequence resets to prevent primary key conflicts
That last one — sequence resets — is the kind of thing that seems minor until it ruins your day. After importing data, if you don't reset the auto-increment sequences, the next new record tries to use an ID that already exists. Instant conflict. It's subtle and it will bite you.
When I self-hosted Trigger.dev, the documentation for self-hosting was thin. The Docker setup had gaps. I spent multiple nights reading through Trigger.dev's source code on GitHub — their Go and TypeScript services — trying to understand why workers weren't connecting or why jobs were silently failing. Eventually I got it working and published the configuration:
coolify-trigger-v4 — complete Docker Compose configs with three deployment options (distributed, single server, external databases), pre-configured for 4 Hetzner server tiers, with security hardening and NVMe-optimized settings.
I also built latest-supabase-coolify-template — because Coolify's built-in Supabase template was outdated and missing production configs. Mine includes automatic JWT generation, production PostgreSQL tuning, connection pooling, and two configurations (dev/staging and production).
None of this was planned. I built these tools because I needed them. Then I realized nobody else had solved these problems either — the communities were asking the same questions with no answers. So I cleaned up the code, wrote documentation, and published.
Self-Hosting in the AI Era
This is the part I'm most excited about, and the part nobody's talking about.
With AI coding tools becoming central to how we work — Claude Code, Cursor, Copilot — there's a massive advantage to having your entire infrastructure defined as code in your repository.
When your infrastructure lives in Docker Compose files, environment configs, deployment scripts, and monitoring configurations — all version-controlled in your repo — your AI assistant can read and understand your complete system. It can see every service, every connection, every configuration. It knows your PostgreSQL is tuned with shared_buffers=8GB and max_parallel_workers=8. It knows your Trigger.dev workers connect to a specific Redis instance. It knows your Supabase instance uses a custom Supavisor pool size.
Compare that to a SaaS setup. Your database config lives in a Supabase dashboard. Your background job settings are in a Trigger.dev UI. Your deployment config is in Vercel's settings panel. None of that context is available to your AI assistant. It's locked behind dashboards that AI can't read.
Self-hosting naturally leads to everything as code. Your infrastructure IS your codebase. And in the AI era, that's not just a nice principle — it's a competitive advantage.
No clicking around external dashboards. No context that only lives in a SaaS UI. Everything version-controlled. Everything reviewable. Everything AI-readable.
The Tooling: Coolify and Dokploy
Coolify has been my workhorse for the past two years. Every Veedoo project, every Baseloop service, all of it runs on Coolify across Hetzner Cloud servers — even ParliamentConnect's ML platform, everything except its GPU jobs. I recommend it explicitly. The open-source community is active, the deployment experience is genuinely good, and it handles 90% of what you need from a PaaS.
That said, I've recently been dipping my feet into Dokploy — another open-source, self-hosted PaaS. What drew me to it is the Docker Swarm setup and their approach to zero-downtime deployments. Dokploy uses Docker Swarm's native rolling update mechanism: health checks verify the new version is ready, the update happens with configurable parallelism and delay, and if the new deployment fails health checks, it automatically rolls back to the previous version. No manual intervention.
I'm not switching from Coolify. But for specific use cases where zero-downtime is critical, Dokploy's Swarm-based approach is worth exploring. The self-hosting ecosystem is getting better every month, and having options is the whole point.
The Philosophy
Self-hosting started as a compliance requirement for one EU project. It became the default for everything.
Here's why: it wins on every axis.
Cost — 70%+ savings compared to equivalent SaaS tiers, with more capability.
Control — Custom configs, custom tuning, custom scaling. No waiting for tier upgrades or support tickets.
Data ownership — Your data lives where you put it. Period.
AI compatibility — Everything as code means your AI tools understand your full system.
Debugging — When something breaks, you can actually fix it instead of waiting for someone else to.
The combination of Coolify (or Dokploy) + Hetzner Cloud + Docker Compose gives you the same developer experience as Vercel or Heroku — deploy from Git, automatic SSL, preview environments — but you own everything.
When you control your infrastructure, you control your destiny. No vendor can rug-pull your pricing. No SaaS can deprecate the feature you depend on. No outage on someone else's platform takes your product down.
That's not just a cost optimization. That's a philosophy.
Check out the tools I built for the self-hosting ecosystem:
- Supabase Sync (npm:
supabase-sync) — Full Supabase instance migration CLI - Coolify Trigger.dev v4 — Self-host Trigger.dev on Coolify
- Latest Supabase Coolify Template — Production Supabase on Coolify
- Self-Hosted Next.js & Supabase Starter Template
Find me on GitHub, LinkedIn, or at taoufiqlotfi.com.
If you're self-hosting your infrastructure — or thinking about it — I'd love to hear about your setup. What tools are you using? What problems did you hit? Connect with me.
End of file
 How I Ship Five Times More With AI
 How I Built ParliamentConnect's ML Pipeline Solo
 Joining Baseloop as a Founding Engineer